SoyNet
The Foundation for a Faster and Lighter AI
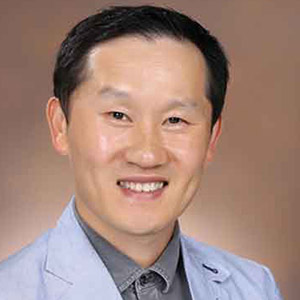 Jung Woo Park, CEO and Co-founder
Mr. Park explains that this imbalance between training and production sub-markets exists due to the heavy and dexterous AI models' nature. To elaborate, developers generally use open source and complex AI frameworks such as TensorFlow, PyTorch, Caffe, and Keras, which could make the AI models unnecessarily convoluted, requiring higher computing power and processing speeds. Park's company—SoyNet—circumvents this hurdle by doubling down on the inference models, focusing solely on the reasoning part, rather than the learning part. Figuratively, the company steers away from the training-related processes by accelerating production speed, thereby eliminating redundancies that could otherwise lead to slower development times. "SoyNet has taken an innovative approach to solving bottlenecks within AI implementations.
We have stripped away the AI training engine (once training has taken place), leaving only an AI inference engine. The result is a much lighter AI accelerator that boots up quickly and takes less memory," adds Mr. Park.
Accelerating AI with inference-only framework
SoyNet has developed an AI inference-only framework that breathes life into intelligent technologies by serving as a simple but highly versatile framework for AI models. The company's AI Inference-only framework adopts 8-bit quantization and post-training techniques to ensure that the developed models are faster and lighter, consuming lesser memory.
SoyNet can execute AI models three times faster than TensorFlow while consuming just one-ninth of the memory. Such a framework proves to be a competitive differentiator for the company, providing 'easy middleware for Java, python and C developers to build AI applications.' The inference accelerator developed by SoyNet helps clients render services without any delay, allowing businesses to expand their footprint by utilizing a combination of AI tools and models. Be it image processing, natural language processing, facial recognition, anomaly detection, or time-series functions, SoyNet's inference accelerator engine drastically cuts short the development time of AI models, irrespective of their applicability.
Accelerating AI with inference-only framework
SoyNet has developed an AI inference-only framework that breathes life into intelligent technologies by serving as a simple but highly versatile framework for AI models. The company's AI Inference-only framework adopts 8-bit quantization and post-training techniques to ensure that the developed models are faster and lighter, consuming lesser memory.
-
SoyNet can execute AI models three times faster than TensorFlow, all the while consuming just one-ninth of the memory
SoyNet can execute AI models three times faster than TensorFlow while consuming just one-ninth of the memory. Such a framework proves to be a competitive differentiator for the company, providing 'easy middleware for Java, python and C developers to build AI applications.' The inference accelerator developed by SoyNet helps clients render services without any delay, allowing businesses to expand their footprint by utilizing a combination of AI tools and models. Be it image processing, natural language processing, facial recognition, anomaly detection, or time-series functions, SoyNet's inference accelerator engine drastically cuts short the development time of AI models, irrespective of their applicability.
More importantly, the company provides easy-to-use, high-level APIs for a multitude of operations; such an approach to development makes AI more comfortable and more intuitive without requiring in-house experts. The demand for such AI applications continues to rise across many environments, such as cloud and on-premise infrastructures, while supporting edge computing operations.
SoyNet facilitates integration across various small edge devices such as Jetson Nano, wherein models developed on desktop ecosystems can be translated to edge computing devices. Such computing capabilities are critical components of a smart factory—within the industry 4.0 umbrella—with edge devices and on-premise solutions playing some of the quintessential roles on the industrial floor. SoyNet excels at customizing solutions for numerous such use-cases, wherein, the development of AI models for specific areas of applicability could be improved exponentially, thanks to the inference-only accelerator. "When you train AI on a workstation for a smart factory, the end-product might not work on edge devices as they consume more memory. What is trained on a high-level PC does not work on entry-level devices, and that is where our inference model proves to be beneficial," Mr. Park explains.
Upholding General-Purpose AI
SoyNet supports the general-purpose AI market extensively. The aforementioned 8-bits quantization technology scales down the conventionally used 32-bit floating-point integer, effectively reducing the memory consumption to carry out specific operations. As this merit also improves processing efficiency, the development of AI solutions for numerous use cases could be accelerated to a great extent, invariably improving developers' productivity, who can save both time and resources during the production phase.
SoyNet facilitates integration across various small edge devices such as Jetson Nano, wherein models developed on desktop ecosystems can be translated to edge computing devices. Such computing capabilities are critical components of a smart factory—within the industry 4.0 umbrella—with edge devices and on-premise solutions playing some of the quintessential roles on the industrial floor. SoyNet excels at customizing solutions for numerous such use-cases, wherein, the development of AI models for specific areas of applicability could be improved exponentially, thanks to the inference-only accelerator. "When you train AI on a workstation for a smart factory, the end-product might not work on edge devices as they consume more memory. What is trained on a high-level PC does not work on entry-level devices, and that is where our inference model proves to be beneficial," Mr. Park explains.
Upholding General-Purpose AI
SoyNet supports the general-purpose AI market extensively. The aforementioned 8-bits quantization technology scales down the conventionally used 32-bit floating-point integer, effectively reducing the memory consumption to carry out specific operations. As this merit also improves processing efficiency, the development of AI solutions for numerous use cases could be accelerated to a great extent, invariably improving developers' productivity, who can save both time and resources during the production phase.
| Share this Article: Tweet
|
Company
SoyNet
Management
Jung Woo Park, CEO and Co-founder
Description
SoyNet supports the general-purpose AI market extensively. The aforementioned 8-bits quantization technology scales down the conventionally used 32-bit floating-point integer, effectively reducing the memory consumption to carry out specific operations. As this merit also improves processing efficiency, the development of AI solutions for numerous use cases could be accelerated to a great extent, invariably improving developers' productivity, who can save both time and resources during the production phase